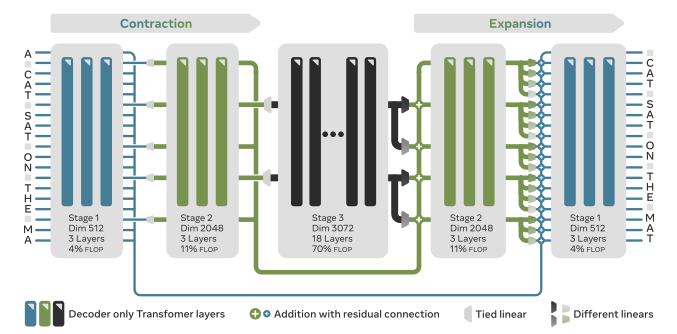
A byte-level language modeling proposal where autoregressive U-Nets learn a hierarchical token representation — no tokenizer required.
A benchmark system for evaluating LLMs across long contexts — summarization, long-doc QA, RAG, re-ranking, and generation with citations — beyond synthetic needle-in-a-haystack tests.
A paper that proposes test-time learnable long-term memory for LLMs, with a 'Surprise' metric that decides what in the context is worth remembering.
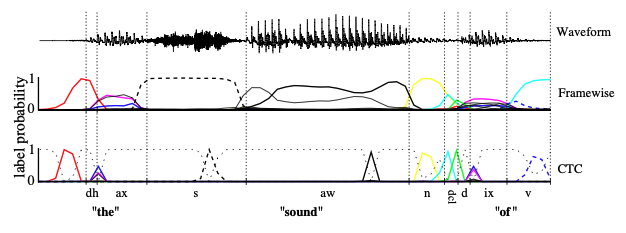
A hands-on look at Connectionist Temporal Classification — the soft-alignment loss that powers speech and OCR models, and the humble 'blank' label that makes it work.
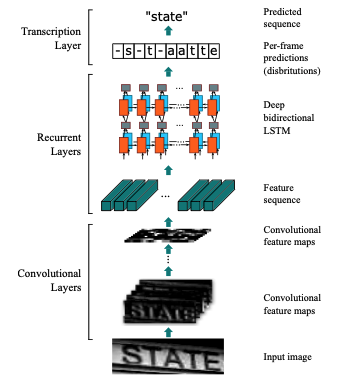
Why Convolutional Recurrent Neural Networks still matter for scene text recognition, handwriting transcription, and speech — even in the VLM era.
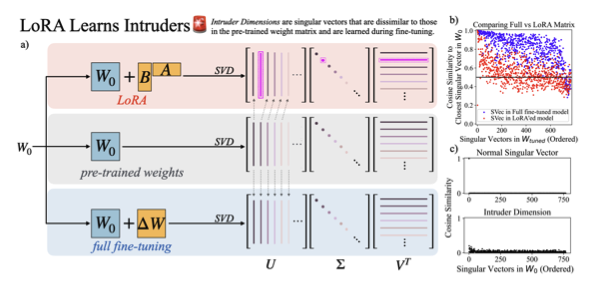
A critical look at how LoRA fine-tuning actually differs from full fine-tuning — and the 'intruder dimensions' that formalize how LoRA silently forgets part of the pre-training.