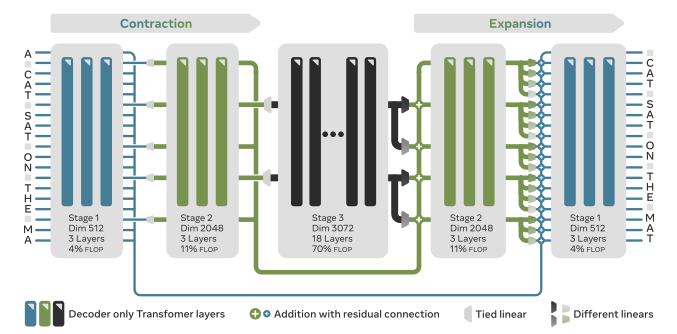
A byte-level language modeling proposal where autoregressive U-Nets learn a hierarchical token representation — no tokenizer required.
A paper that proposes test-time learnable long-term memory for LLMs, with a 'Surprise' metric that decides what in the context is worth remembering.